

Data Pipeline Overview
A data pipeline is a set of operators arranged by their dependencies that turns raw recordings into structured data. Each run is a processing job with its own pipeline job ID, progress, logs, and outputs.
When You Need a Pipeline
| Data | Pipeline required? | Why |
|---|---|---|
| RAW (Robot-free Ego, Robot-free UMI) | Required | RAW contains only raw sensor data. Operators must produce structured data such as trajectories, depth, and keypoints before it can be curated or used for training. |
| HDF5 (Station Lite, MOS) | Optional | HDF5 already includes robot state and can be curated directly. Run a pipeline only when you need additional visual or depth information. |
Operator Types
| Type | Input | Typical outputs |
|---|---|---|
| SLAM | Stereo video, IMU, calibration | Camera trajectory and pose sequence |
| Vision | Video frames | Object detection boxes, segmentation masks, hand keypoints |
| Depth | Stereo or monocular video | Per-frame depth maps |
| Tactile | Tactile sensor signals | Aligned tactile sequences and features |
| Multi-operator | Any combination of the above | Multiple output types |
R&D engineers upload operators to the project's operator library. You can use the operators provided by the platform or write your own following Developing Operators.
Pipeline Chain
Every pipeline is shown as three stages:
text
Prerequisites ──▶ Operator execution ──▶ Post-processing
(decoding, time      (selected operators run      (formatting, writing back to
 alignment,           in dependency order)          the asset pool, generating
 loading calibration)                               previews)
Processing Jobs and Outputs
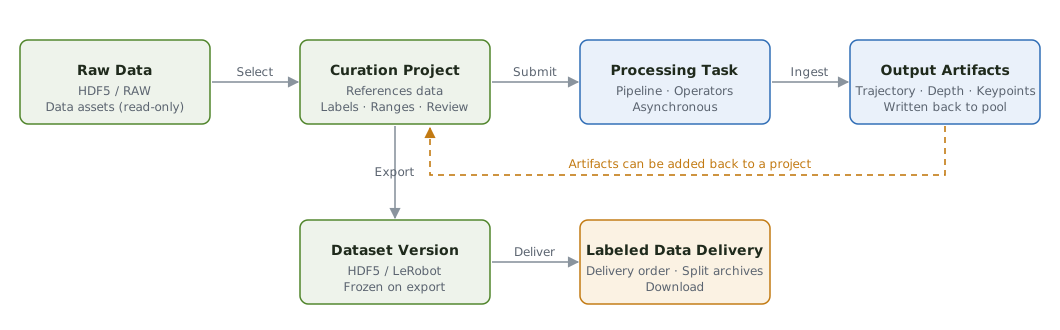
- A processing job is started from a curation project and processes the items selected in that project.
- Processing is asynchronous, so you can leave the page after submitting.
- A job completes only when every required operator succeeds. Otherwise the whole batch is marked failed, and you can retry the failed steps.
- Outputs are written back to the asset pool, tagged with the pipeline job ID. The original data is preserved.
- Outputs can then be labeled and reviewed in the workbench and exported as a dataset version.
In This Section
Running Processing JobsOpen the pipeline dialog, select operators, submit, track progress, and handle failures.Annotated Data and DeliveryWhat annotated data contains, and how to review, export, download, and deliver it.Developing OperatorsPackage layout, descriptor file, runtime contract, and local testing.